Published · By Henry Palma
Databricks Data Engineer Associate Exam Prep, Lesson 4: Auto Loader Schema Evolution
Databricks Data Engineer Associate exam prep, Section 2: Auto Loader schema evolution, schema hints, mergeSchema, and why a new column fails the stream once.
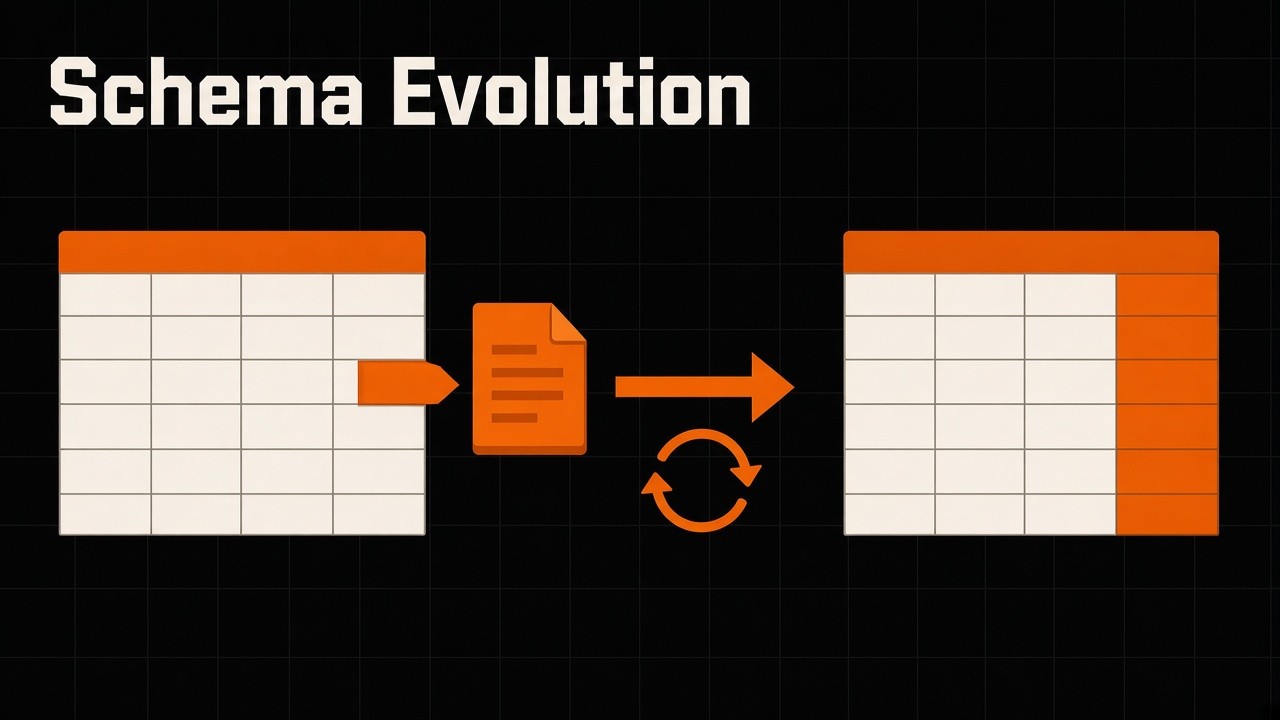
Exam-style question: an Auto Loader stream runs with the default settings, and a new file arrives with an extra column. What happens on the next run? The stream fails once, after Auto Loader records the new column at the schema location. Restart it, and the new column is picked up. This post follows Lesson 4 of the Databricks Data Engineer Associate exam prep series, in Section 2 of the August 2026 exam guide, Data Ingestion and Loading (21% of the exam).
The notebook and cheat sheet are in the A04 folder on GitHub. The PDF cheat sheet is in the same folder. This is independent study material, not official Databricks training.
The exam objective
Use Auto Loader with schema enforcement and evolution. The lesson covers schema inference, schema hints, the rescued data column, the schema evolution modes, and merge schema on the write. Everything runs in Databricks Free Edition, with a Unity Catalog volume as the source, a serverless notebook, and trigger availableNow.
The earlier Auto Loader basics are in the Auto Loader tutorial and Lesson 2. Lesson 3 covers COPY INTO. This lesson starts at schemas.
schemaLocation turns on inference and evolution
In a Python notebook on Serverless, cell 1 creates a new schema (btautoloader plus 12 random hex characters) and two volumes: landing for the source files and checkpoints for the stream checkpoint and the schema location. Cell 2 writes a fictional ordersday1.csv with three orders and the columns orderid, customer, amount, and order_date.
Cell 3 only looks at the inferred schema. It does not start a stream:
df = (spark.readStream.format("cloudFiles")
      .option("cloudFiles.format", "csv")
      .option("cloudFiles.schemaLocation", chk)  # schema kept in chk/_schemas
      .load("/Volumes/workspace/bt_autoloader_xxxx/landing/orders"))
df.printSchema()
The cloudFiles.schemaLocation option is what turns on schema inference and schema evolution. Auto Loader samples the files (the first 50 GB or 1,000 files) and stores the schema it infers in an _schemas folder at that location, so it can track changes over time. The schema location can share the checkpoint folder.
Default inference: every column is a string
For CSV, JSON, and XML files, Auto Loader infers every column as a string by default, plus an extra rescueddata column. It does that so a changing value cannot break a column type later. Parquet and Avro take their types from the file schema.
You should expect orderid and amount to come back as strings on this first peek. Auto Loader adds rescued_data automatically when it infers the schema.
inferColumnTypes and schema hints
The real stream, wrapped in a run_bronze function so it can run again, turns on typed inference and pins the types you already know:
(spark.readStream.format("cloudFiles")
  .option("cloudFiles.format", "csv")
  .option("cloudFiles.schemaLocation", chk)
  .option("cloudFiles.inferColumnTypes", "true")
  .option("cloudFiles.schemaHints", "amount DECIMAL(10,2), order_date DATE")
  .load(src)
  .writeStream
  .option("checkpointLocation", chk)
  .option("mergeSchema", "true")
  .trigger(availableNow=True)
  .toTable("orders_bronze"))
cloudFiles.inferColumnTypes set to true gives typed columns, the way the regular Spark reader infers them. Schema hints (cloudFiles.schemaHints) apply on top of the inferred schema. They can also add a column that has not appeared yet, and they only work when you do not provide a full schema with .schema(...).
On the write side, mergeSchema set to true lets the Delta table accept new columns. Trigger availableNow processes the files that are there, then stops, which is the serverless-friendly way to run the stream.
The first run should load 3 rows with real types: orderid as an integer from inference, amount as a decimal and orderdate as a date from the hints, and rescueddata still at the end.
A new column arrives, and the stream fails once
Cell 6 writes a day 2 file with a new column, channel. Order 1005 also has amount set to N/A, which is not a decimal. That is two different schema problems in one file.
Run the same stream again. With the default schema evolution mode, addNewColumns, the stream stops with an UnknownFieldException for channel. Before it fails, Auto Loader merges the new column into the schema stored at the schema location. The existing column types do not change. No rows from day 2 were written yet, so the table still has 3 rows.
That is the answer to the opening question. The stream fails once, after it records the new column. Restart it, and it picks up the new column. In production, Databricks recommends running Auto Loader in Lakeflow Jobs, set to retry, so the restart happens automatically.
Restart, mergeSchema, and the rescued data column
Cell 8 runs the exact same code again. This time Auto Loader reads with the updated schema, so day 2 loads and the table has 5 rows. This is where mergeSchema on the write matters. The stream now carries a channel column the Delta table does not have. Without mergeSchema set to true, the write fails with a schema mismatch. With it, the table gains the new column.
The three day 1 rows should show null for channel. Order 1004 loads normally. Order 1005 has a null amount, but the original value is not lost. The rescued data column (rescueddata) holds a small JSON blob with amount set to N/A and the path of the source file.
Three kinds of values land in rescueddata:
- Type mismatches, like
N/Ain a decimal column - Columns that are missing from the schema, which you will see in rescue mode
- Case mismatches, like a capital
Amountcolumn
The blob is stored as JSON, along with the source file path, so you can fix the data later instead of losing it. With a rescued data column, a type mismatch does not fail the read. Only truly malformed records do. You can rename the column, or add it to a provided schema, with the rescuedDataColumn option.
Five schema evolution modes
The option cloudFiles.schemaEvolutionMode picks the behavior when a new column shows up:
addNewColumnsis the default. The stream fails once, adds the column, and resumes on restart.addNewColumnsWithTypeWideningdoes the same, and also widens types, like integer to long. It is in public preview.rescuenever evolves the schema and never fails. New columns go into the rescued data column.failOnNewColumnsstops the stream, and it stays stopped until you update the schema or remove the file.noneignores new columns, never fails, and does not rescue them unless you set a rescued data column.
Provided schema versus schema hints
If you provide the full schema with .schema(...), the default mode becomes none, and addNewColumns is not allowed. New columns are ignored. That is strict enforcement, and you can set the rescuedDataColumn option to keep values that do not fit.
If you infer the schema and add schema hints, the default stays addNewColumns. Hints pin the types you know, they can even add a column that has not appeared yet, and evolution still works.
Five exam traps
- CSV and JSON columns are inferred as strings, unless you set
cloudFiles.inferColumnTypes. - In the default mode, a new column makes the stream fail once, and a restart picks it up.
- Rescue mode never fails and never adds the column.
- With a provided schema, the default mode is
none. - To add the new column to the Delta table, set
mergeSchemaon the write.
Practice challenge
After cell 8, a day 3 file lands with another new column, coupon.
- You call the same
run_bronzefunction, in the default mode. What happens on the next run, and what happens after that? - A different stream, set to rescue mode, reads day 3. Does it add a column, and does it fail?
- A stream with a provided schema, and no mode set, reads the file. Which mode applies, and where does
coupongo?
Answers: (1) The run fails once with an UnknownFieldException for coupon, and the schema location is updated. Run it again, day 3 loads, and mergeSchema adds coupon to the table. (2) Rescue mode does not fail and does not add a column. The coupon values go into the rescued data column. (3) With a provided schema, the default mode is none. coupon is ignored, the stream does not fail, and the values are not rescued unless you set the rescuedDataColumn option. The solution cell is commented out in the notebook.
Key takeaways
cloudFiles.schemaLocationturns on inference and evolution.inferColumnTypesand schema hints give you real types.- The default mode fails once on a new column, and a restart with
mergeSchemaadds it to the Delta table. - The rescued data column keeps values that do not fit.
Check your understanding
1. An Auto Loader stream runs with the default settings. A new file arrives with an extra column. What happens on the next run?
- A) The new column is added and the file loads on that run
- B) The stream fails once, after the schema location is updated; a restart picks up the new column
- C) The new column is ignored
- D) The new column goes into
rescueddataand the stream keeps running
2. For CSV and JSON, what types does Auto Loader infer by default?
- A) Integers and doubles
- B) The same types as the regular Spark JSON reader
- C) Every column as a string, unless
cloudFiles.inferColumnTypesis true - D) Whatever you listed in
.schema(...)
3. A stream is set to rescue mode, and a file arrives with a new column. What happens?
- A) The stream fails once, then adds the column
- B) The stream stays failed until you update the schema
- C) It never fails and never adds the column; the new values go into
rescueddata - D) The Delta table gains the column even without
mergeSchema
4. You provide a full schema with .schema(...) and do not set a mode. Which schema evolution mode applies?
- A)
addNewColumns - B)
rescue - C)
failOnNewColumns - D)
none
5. After a restart, the stream carries a new column the Delta table does not have. What lets the table accept it?
- A)
cloudFiles.schemaHints - B)
mergeSchemaon the write - C)
cloudFiles.inferColumnTypes - D)
rescuedDataColumn
Answer key
- B. Default mode
addNewColumnsfails once with anUnknownFieldExceptionafter updating the schema location; the restart loads the new column. - C. CSV, JSON, and XML columns are inferred as strings unless you turn on
inferColumnTypes. - C. Rescue mode never evolves the schema and never fails; new columns go into
rescueddata. - D. A provided schema changes the default mode to
none, andaddNewColumnsis not allowed. - B. Without
mergeSchemaon the write, the restart fails at the Delta table with a schema mismatch.